Migrating Exchange Online Protection from EWS to Microsoft Graph: Post Your Questions Here
Ask questions. Find and share technical expertise, configuration tips, resilience best practices and more.
Recently active
Good Day,We have two Microsoft Office 365 Index Servers configured in a load-balanced setup.The index disk on Index Server A became full, so I ran the Load Balance Index Server workflow. After the workflow completed, the index data was moved/copied from Index Server A to Index Server B.Since then, we have been experiencing issues accessing the Index Server and index-related operations are no longer functioning correctly.Could you please clarify:Why are the Microsoft Office 365 backup indexes not automatically distributed across both Index Servers when load balancing is configured? What is the recommended method to rebuild or recover the indexes after running the Load Balance Index Server workflow? How can we restore normal Index Server operation in this scenario?We are running on SP 11.40.67 Error: Exchange index stats failed for subclient [4107] with message [Exception of type 'Commvault.InfoRetrieval.SearchServerException' was thrown.] Unknown error, Webserver failed to process Idx
I am currently questioning our AuxCopy to tape performance and want to get some input on how to identify the bottleneck.We have multiple plans which all have two copies to tape. One is synchronous and one is selective.Each of the two is consolidated onto another Global Secondary Copy Policy.The storage target are six LTO9 drives with a mixed LTO8 and LTO9 media inventory.The source for the copy is a NetApp StorageGRID S3 backed storage pool with deduplication connected on a 100G fiber network.We have two Media Agents which are both connected to all LTO drives and the NetApp (same VLAN).Looking at the reported speed of the drives in Commvault I get around 130MB/s all of the time.I could confirm this looking at SFP speeds on the FC switch which also stay around this value with rare peaks to around 200MB/s.What I tested already to look for the bottleneck:- only run one AuxCopy Job- run AuxCopy when no other jobs where running- validate drive > 300MB/s throughput with LTO8 media- differ
Hello Team,We are currently using HP LTO7 and LTO8 media with our Commvault environment.Could you please advise if there is any recommended limit on the number of times these tapes should be reused? Also, are there any Commvault or HP best practices regarding tape media reuse, such as a recommended maximum number of write/overwrite cycles or media retirement criteria?We would appreciate your guidance on the recommended approach to ensure media reliability and avoid any potential data integrity issues.Thank you for your support.
According to the documentation for the disk caching for log backups feature, the CommServe computer does not need to run frequent backup jobs throughout the day. Instead, log files are backed up at the desired frequency using native backup utilities, cached to a mount point on the MediaAgent, and made available for database restores. The Scheduler then runs at the interval defined by the "Use disk cache for log backups and commit every" setting to commit the cached data.I understand that the cache resides on the backup storage associated with the primary copy of the backup plan and that Commvault handles this automatically when caching is enabled.However, the documentation does not specify the directory path where these logs are saved. Could you please clarify where exactly the logs are stored on the MediaAgent during the dump phase?
I passed the Commvault Cloud Professional Certification today and the badge is not showing up on Credly.
Dear All, I am trying to build a HyperScale X Lab in our office. I am using sp40_13_hsx_prod_dvd_09152025_061956.iso it is failing on Creating Building Storage Configuration. Please assist.
Hello guys,we have installed a new Commvault environment for a customer a few months ago. The customer now says he wants encryption enabled for all backups. I found the option “Create new DDB every 30 days” in the deduplication engine settings and was wondering if that can solve our problem.In my understanding, this option will write every backup after 30days as new blocks which also should make them encrypted. So my question is:can I just enable encryption on the DDB engines and check the “Create new DDB every 30days” box and keep everything else running? Will this solve our encryption problem? Thanks in advance
Hi everyone,We are deploying a HyperScale X cluster using three Lenovo ThinkSystem HS350X V3 nodes.I’ve run into a technical infrastructure question and would like to know if anyone here has configured this specific model. The HSX documentation requires the operating system to be installed on a mirrored volume (RAID 1). Our servers are equipped with two M.2 NVMe SSDs for the OS.This Lenovo model's motherboard uses Intel VROC to manage NVMe RAID, but I’ve seen notes indicating that VROC is not supported by HyperScale X.For those who have deployed HyperScale X on similar hardware (without a dedicated hardware RAID controller for the M.2 drives):How did you handle OS mirroring?Did you enable VROC anyway, and did the ISO install without issues?Or did you leave the M.2 drives in Passthrough/JBOD mode and let the Commvault installer handle software mirroring (mdadm) during the boot drive formatting process?Any tips or shared experiences regarding the preparation of this Ready Node would be g
We want to migrate jobs from one S3 cloud library to another S3 library without DDB, avoiding the use of auxiliary copies or data path moves. We aim to use an internal bucket-to-bucket copying mechanism to avoid standard data egress and ingress—thereby reducing egress costs, even though the transfer itself will still incur a charge. Once the data has been copied, we will import the metadata to ensure the backup chain remains consistent for future restores.
Hi Commvault community, We are currently configuring Microsoft Teams user chat backups through Commvault and would like to clarify the current requirements regarding the Microsoft Teams Export APIs.According to Microsoft documentation, starting August 25, 2025, Teams APIs are no longer metered and no billing configuration is required:https://learn.microsoft.com/en-us/graph/teams-licensesThe Microsoft documentation also states that the Teams Export APIs are no longer subject to metered billing.However, in Commvault Command Center we still have the option “Enable this app to use paid Export APIs”, and the current Commvault AI guidance still instructs us to enable this option for Teams user chat backups.Could someone please confirm the current Commvault behavior/requirement?Specifically:Is enabling “Enable this app to use paid Export APIs” still required for Teams user chat backups? Does enabling this option currently result in any Microsoft/Azure API charges? Is the option still required
Hello Community ! I have environment 11.40.72 that I want to upgrade to 11.44(because of EWS deprecation) ,can I backup servers 2019 or 2012R2 or 2016 or 2008R2 that have agent of 11.32 or 11.28 , in 11.44 version? Thanks.
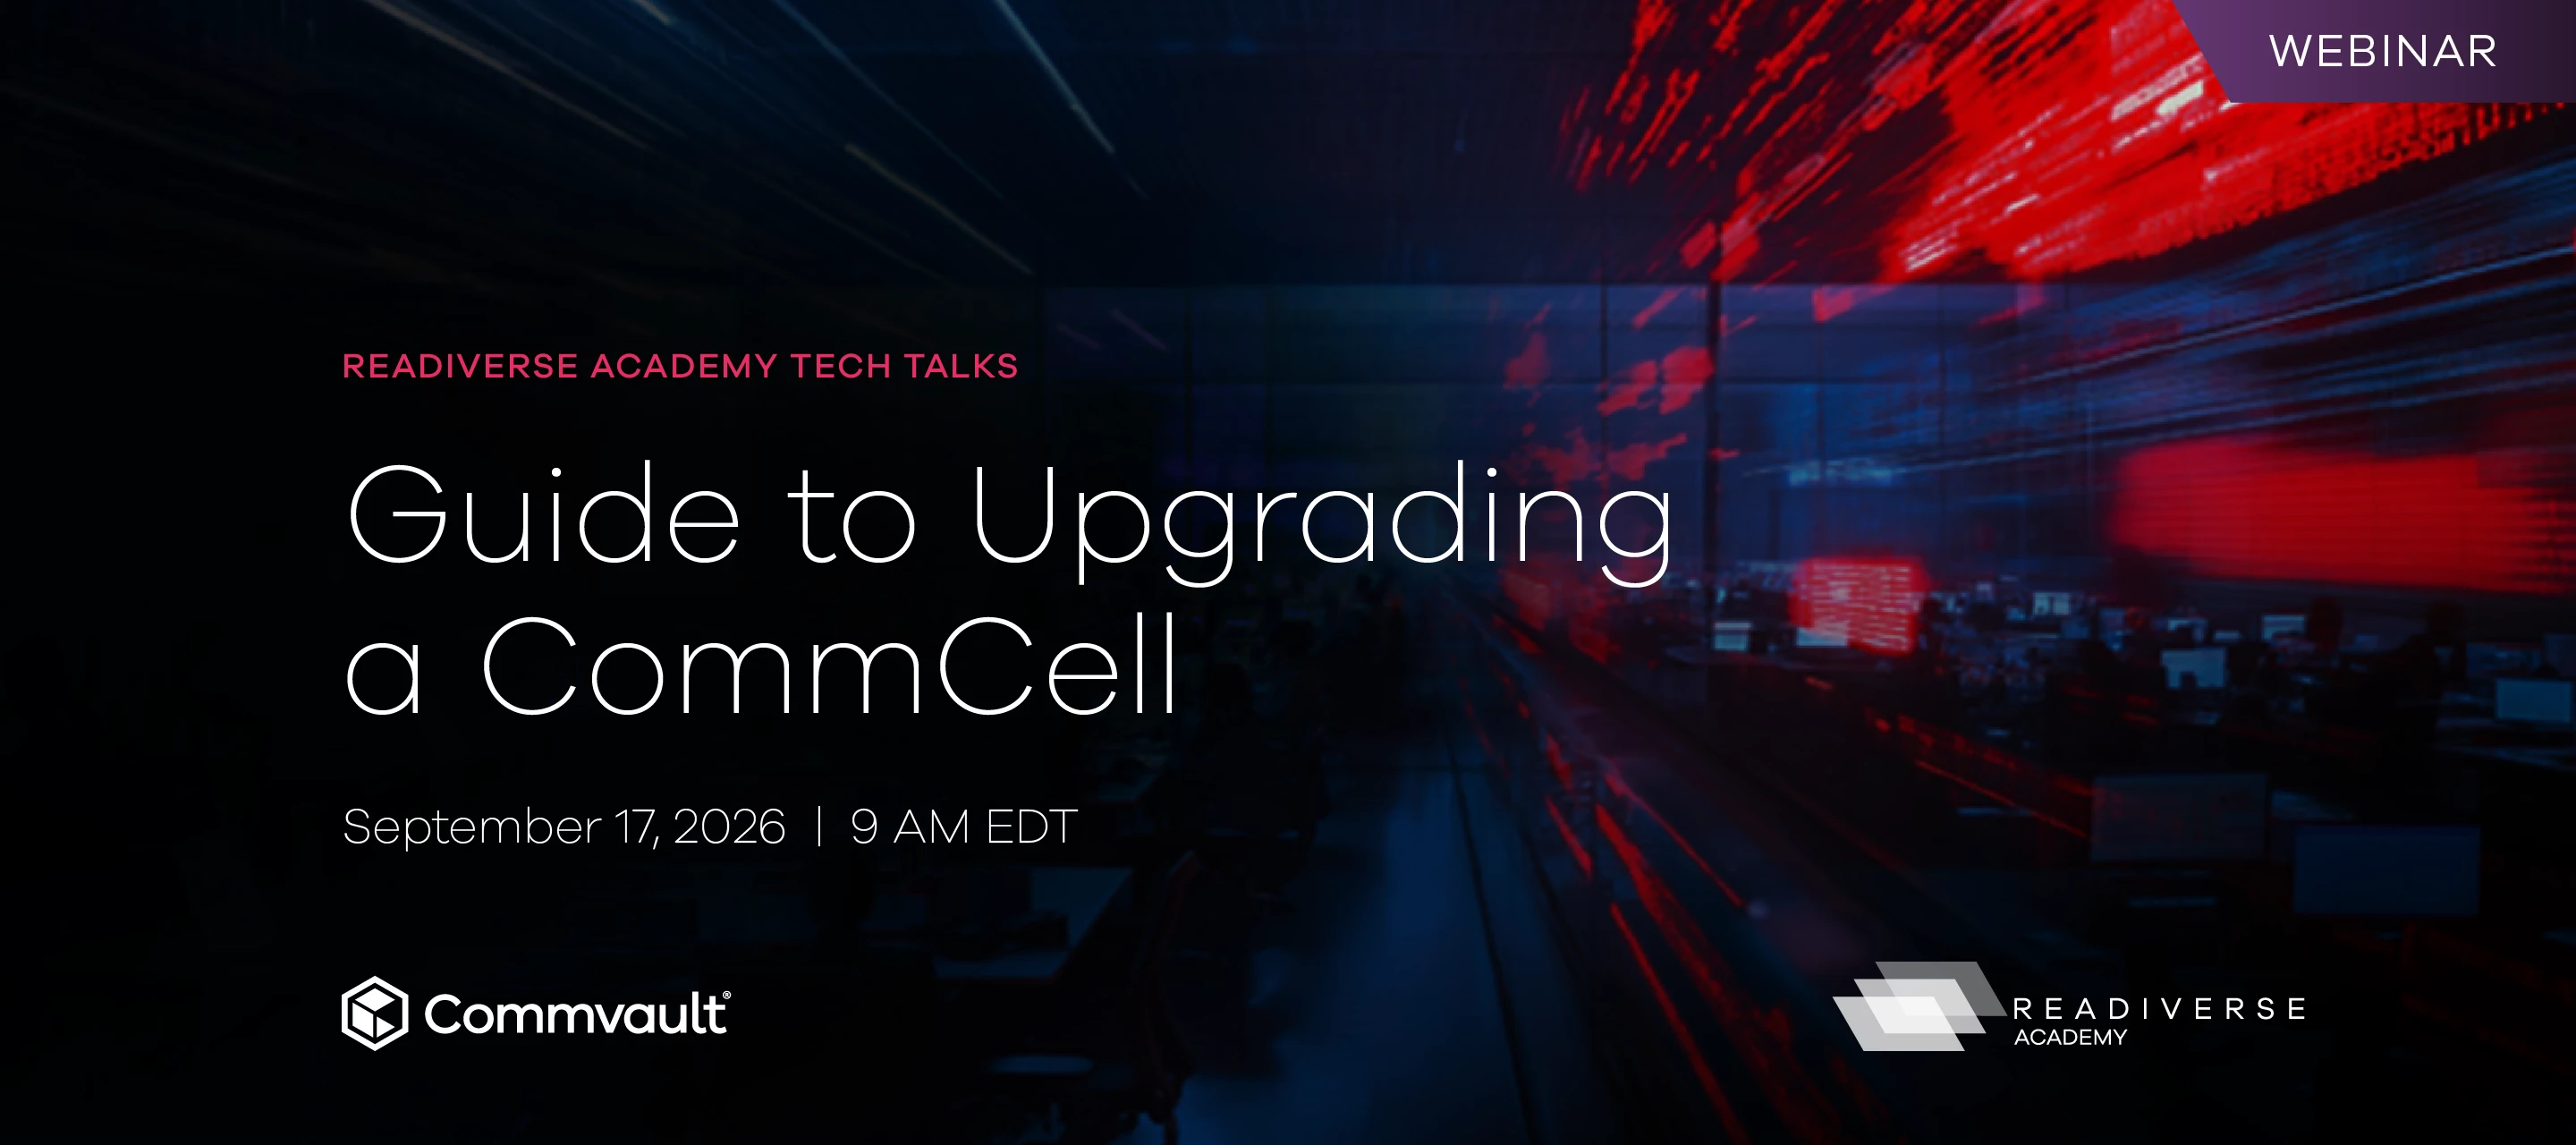
Join Commvault's veteran support engineer Brian Bruno on our next Readiverse Academy Tech Talk for a practical walkthrough on how to plan and execute CommCell upgrades with less disruption. We’ll cover how to evaluate release tracks, prepare before the upgrade window, use Command Center and Server Groups for controlled rollout, and validate your environment after the change.You’ll learn more about How to understand current Commvault release tracks and choose the right upgrade path for your environment. Why Maintenance Releases should be treated as a recurring security and operational practice, not optional housekeeping. How to plan a CommCell upgrade as controlled change across inventory, target release, staging, execution, and validation. What to check before the upgrade window, including system requirements, software cache, job state, DR posture, stakeholders, and validation criteria. How to use Command Center and Server Groups to deploy updates in controlled waves and verify complet
Hi All, i have an problem with my nutanix ahv vsa backup. I git the message: Failed Virtual machine [xyz] was not found. Please verify that the virtual machine still exists and that the host is in the connected state. If the virtual machine does not exist remove it from the subclient. If the virtual machine does exist reselect the virtual machine and re-add it to the subclient content. When i do an browse i found ths maschines. Also under prism central the vms are up and running. I created an test subclient with this vms but doesnt help. Do you have an idear ?
I was using version 11.28, and last week I upgraded to version 11.40.67.Backups after the upgrade work without any problem, but when the 'Commcell Console' outputs a backup report in XML format, the Client Group is not displayed correctly. How can we resolve this issue
the message on the screen just says please wait while our servers start up this may take a few minsits been like this for a while, i have restarted the mango servers and the webservice and have reboot the systems and looked into the registry for HKLM\SOFTWARE\CommVault Systems\Galaxy\Instance001\WebConsole\baseURL).i have also run http://localhost:81/SearchSvc/CVWebService.svc which comes back with a failed webpage load so i am assuming it might be something to do with the .NET framework, the only issues is that is in on a air gapped network with no access to the internet, so i would have to download the correct .NET framework for this version i would include screen shots but for this i have do a lot of paperwork to info off the system. and redact a lot of stuff.any suggestions s would be very welcome :)
This longstanding advisory is being replaced by a new FAQ thread as of September, 2026 to provide clean guidance based on the latest transition support information from Microsoft and the Commvault Product team. Please consult the new thread for the most current KB articles and recommendations and add your questions there for our team to review. - Commvault Support & Community team Watch this brief overview summarizing key phases, dates, and configuration steps to take in your environments. Consult the (new) step-by-step documentation for recommended steps to take to review your environments, ensure continuity of Exchange Online backups through this phased EOS transition and migration, and validate Microsoft Graph readiness. Microsoft has announced the retirement of Exchange Web Services (EWS) in Exchange Online, with phased EWS disablement scheduled to begin on October 1, 2026.For our customers and partners backing up Microsoft 365 and Exchange Online in your environments, please
Hi Everyone,Have you started using Command Center in the last 6 months? We’d love to hear how it’s going! We have a new UX Design Feedback study for community members who have started using Command Center within the last 6 months.Check out the new study blog Sign up formAnd if this study isn’t the right fit for you, please help us spread the word and share it with someone who might be a great fit!Keep an eye on the Community; we’ll have more opportunities to share feedback coming your way. Thank you!Roy, Jenn & Damian | The Community Team
Hello all!In our environment, we have created a temporary copies within our few storage policies - (call them copy 6 and 7). Those were tape copies. We have keep some backup there for 2 months, but it is no longed needed. We do not need those copies within those storage policies any more. But for now, even if they are no longer any backup retained on this 6-7 copy, we do have a lot of “Big Data Apps” jobs retained on those copies.We would like to delete those copies because it interferes with our “workflow” which picks jobs for copies and it's keeping to mark them to copy for 6-7 copy. (even if copy is disabled) So my question is - what exactly this Big Data Apps is? It is some kind of Index, am I correct? If those “Big Data Apps” are stored on copies 6-7 are there any dependencies for other copies, other jobs keep in other/same storage policies?Can we just delete copy 6-7 from our storage policies even if they are still those Big Data Apps stored on it, and it won't affect the rest of
Hello Community ! I have environment 11.32 that I want to upgrade to 11.40 ,can I backup servers 2012R2 or 2012 or 2008R2 that have agent of 11.32 on 11.40 environment? Thanks.
How can Commvault be configured to write backups to tape media? (Note: I have already added the tape and can see the drives and media; I have two drives and three tapes, as well as two backup plans. However, while one plan always succeeds, the second consistently results in errors [32:690] and [32:193].)
Hi guys,I’m currently evaluating / planning the migration from a Windows CommServe to a Linux CommServe.We are using a Fujitsu ETERNUS CS8000 virtual tape library with VJUK (generic SCSI library) emulation as Tape backend.The Workflow (Prefetch Tapes for Restore) provided by Commvault to prefetch media, that have been migrated from cache, is no longer working on Linux CommServe.The Command ManualPrefetchTapes.exe, that is called by the workflow on Windows, cannot be found in the Linux distribution.Can someone tell me where to get it ?Or is there a newer version of the prefetch workflow available, that does no longer use the external command to initiate the prefetch ?Currently running on V11.40.59BRKlaus
Hello,I have an issue with displaying some informations in command center.Some data like Commserve Name, Version oraz data about top 5 largest servers on dashboard displays xxxx instead of the real values.Do you guys have an idea what can be wrong here?Temporarly I have two commserve’s in live sync - old one on Windows and new one on Linux. The issue is present only when active commserve is a linux one (new one). I planned to reinstall this windows also and make both commserve’s on linux, but i’m not sure if this is a good idea doing it and having this issue.Thanks in advance for help.Regards,Mateusz
Hi Commvault experts! Two things I'd like to have confirmed: Firstly, am I right that laptop backup plan is basically incremental forever? As far as I understand it, the client only ever sends changes and full backups are created as synthetic fulls on the storage side, so the endpoint never uploads a full backup overthe network. Is that correct? Secondly, I'm not clear on how retention works once a secondary copy is added. In the laptop plan you set deleted item retention and file versions, but the storage policy behind the plan has its own copies with their own retention settings. So which one actually applies - does the plan drive retention for both copies, or does the plan only cover the primary copy while the secondary copy is governed by the storage policy copy settings?Related: is the auxiliary copy schedule independent of the plan's RPO, or is it tied to it in some way?Thanks!
So I started the Commvault Cloud Practitioner learning plan, and now I am on ‘Security and Compliance’ module.I don’t know if it’s related, but my issue did begin after I tried to watch the course on my mobile phone. I completed the ‘Securing Access: Control, Verification and Approval’ and ‘Protecting your data: Encryption, WORM and Audit Trail’, but their status remains ‘In Progress’. What can I do to resolve this?
how make the commvault write backup on tape media (note: actually i added the tape and i can see the drives and tape media and i have 2 drives and 3 tape media and i have 2 plans but one plan only that always is success job and the plan number 2 give me error [32:690] , [32:193] )
Already have an account? Login
Enter your E-mail address. We'll send you an e-mail with instructions to reset your password.